About the author
Darko Špoljarić
VP of AI
Most writing about evaluating LLM applications is really about evaluating a single prompt. You have an input, an output, a grader, and you run it a few hundred times to get a number for a dashboard. That model is clean, well-supported by tooling, and it has almost nothing to do with the problem we actually had.
We were building a real agent. Commands, subagents, skills, a multi-phase build pipeline on top of the Claude Agent SDK. The thing it produces is a structured domain object assembled across several phases, where each phase writes files to disk that the next phase reads and builds on. Evaluating that is a different sport. This post is about what we tried, why three well-known tools didn’t fit, why a fourth came close, and why we built our own harness anyway.
The agent under test
Strip away the domain and the shape is simple. The agent is delivered as a plugin. It exposes slash commands. Each command drives one or more subagents. Those subagents pull from a library of reusable skills and a pile of reference material: templates, conventions, best-practice docs. Everything runs through the Claude Agent SDK, so the unit of execution is a query() against a prompt with a set of options, not a single chat completion.
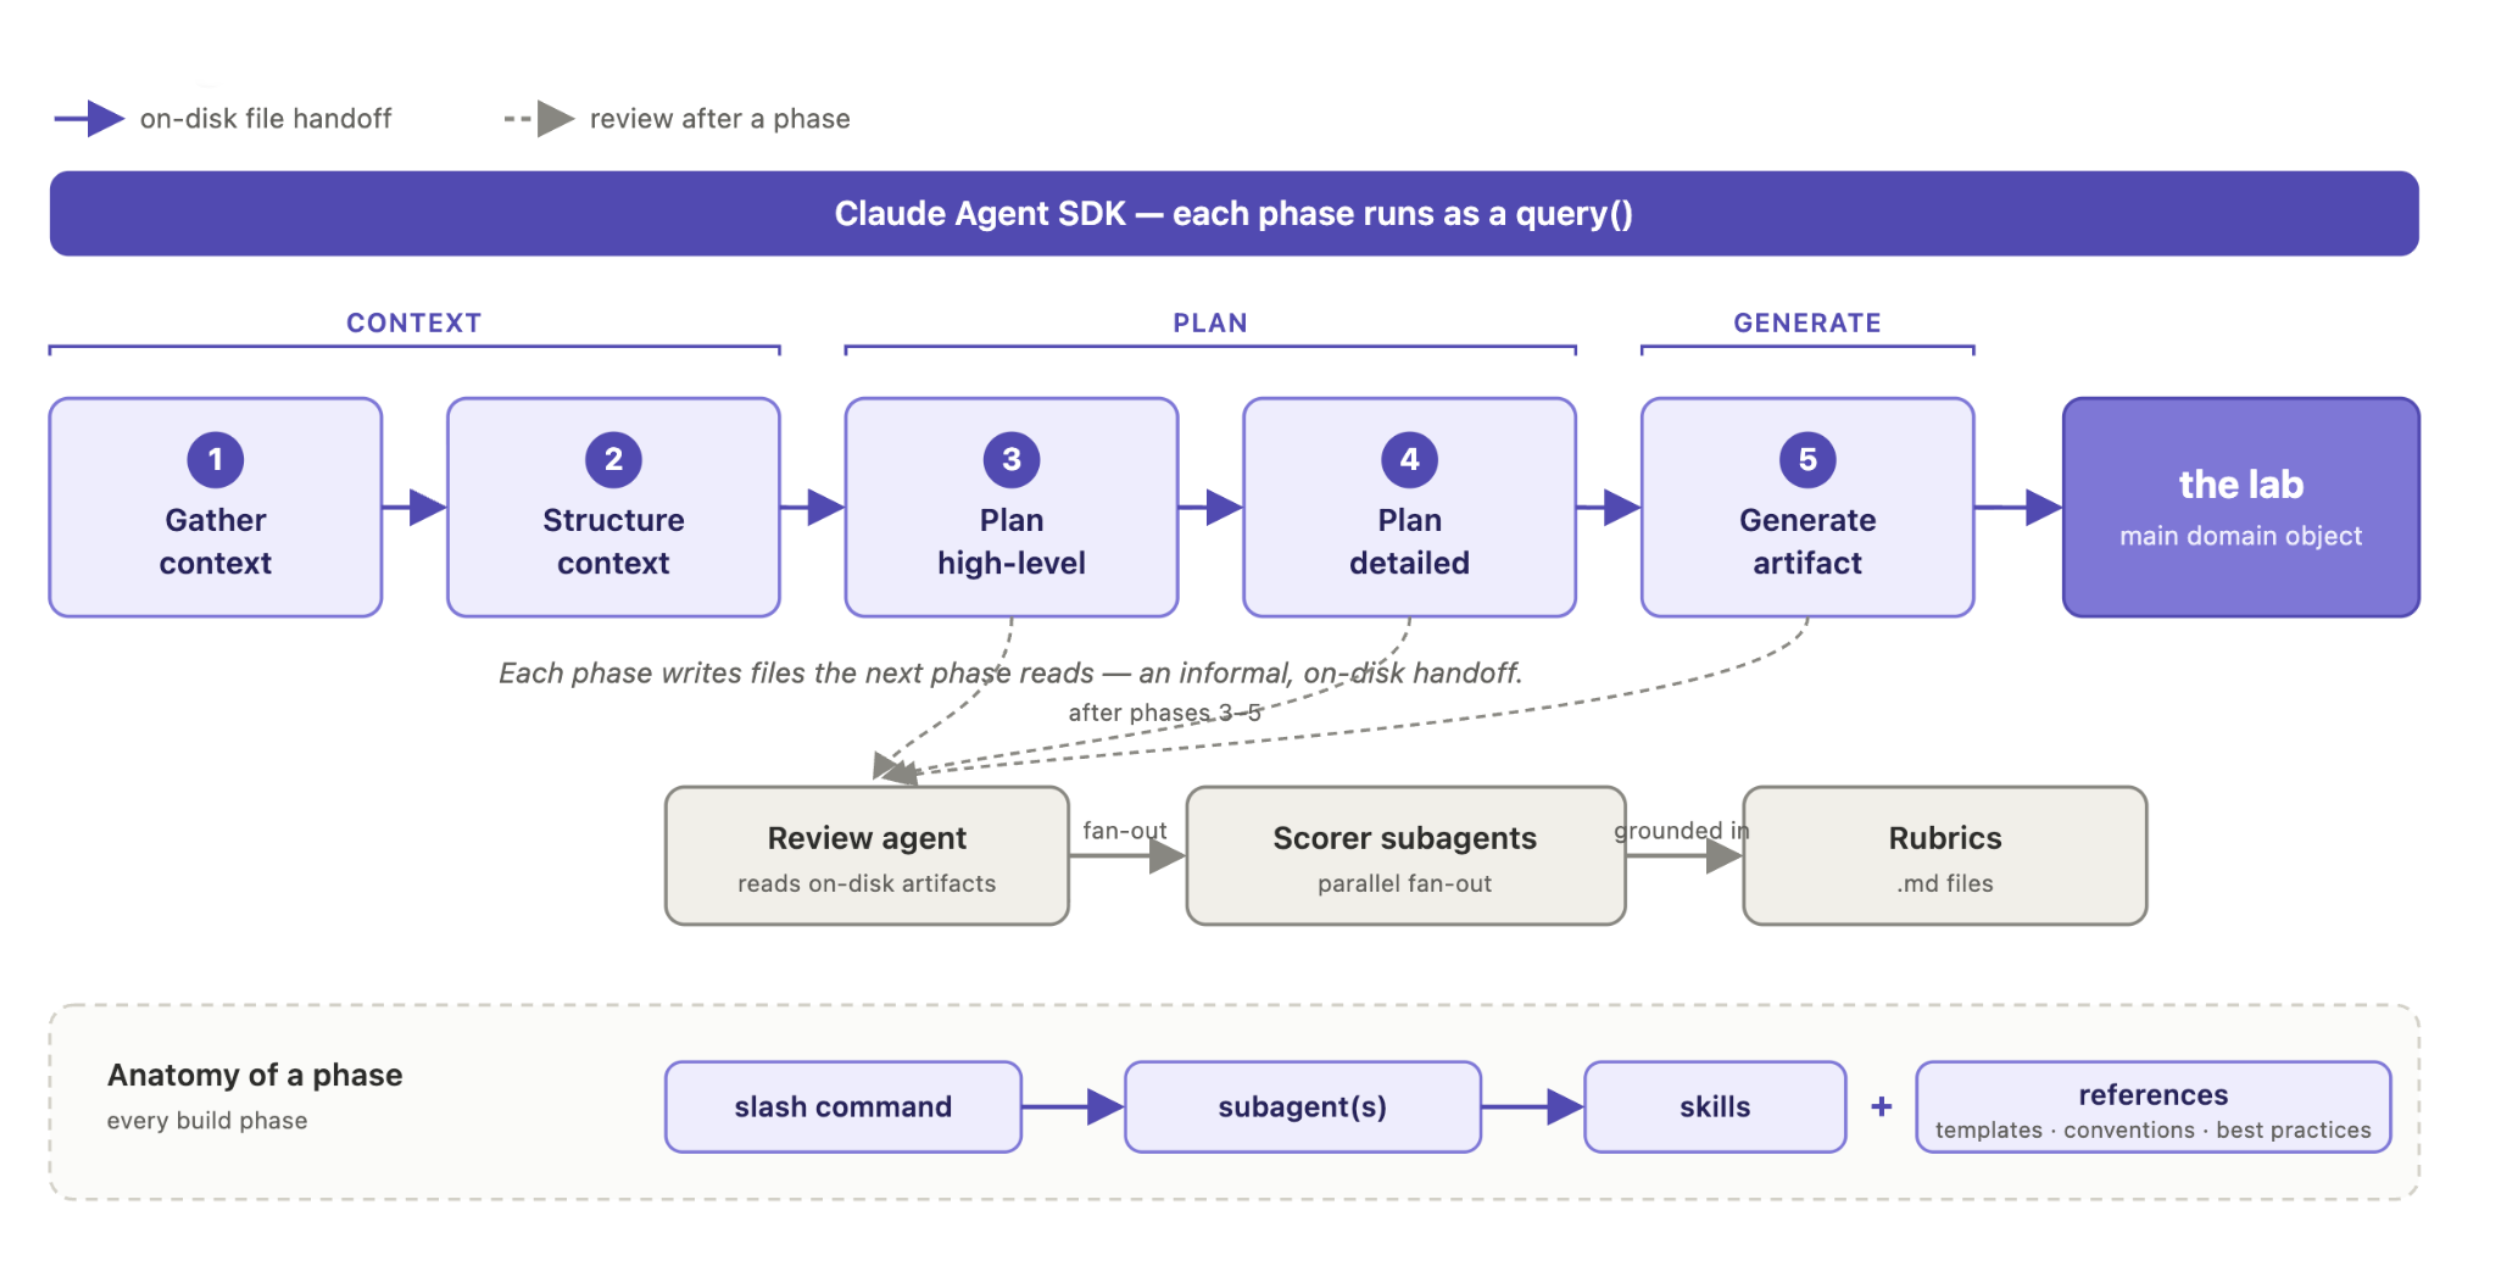
The critical structural fact: the agent builds its main domain object in phases. Five build phases. The first two gather and structure context. The next two plan the object, first at a high level, then in detail. The last one generates the final artifact. Each phase is a self-contained stage that depends on the on-disk output of the stages before it. Phase four can’t run unless phase three has already written a plan to disk. Phase five can’t run without phase four’s detailed plan in the workspace.
On top of the build phases sit reviewer agents. After planning and generation, a review agent scores the output. Reviewers don’t fix anything. They read what was produced, dispatch a fan-out of scorer subagents, and emit a structured scorecard. The foundation of the reviewers is a set of rubrics: markdown files that define criteria and the meaning of each score level. A reviewer is essentially a dispatcher that points scorer subagents at specific rubric files and collects their judgments.
What we needed from an eval tool
- The agent has to run inside a populated working directory. Because the build is phased, you can’t evaluate a later phase in isolation unless you can drop it into a folder that already contains the upstream outputs. An eval that only feeds the agent a prompt string and inspects the reply doesn’t work for us. Most of our phases produce and consume files.
- We needed to evaluate output artifacts, not conversation transcripts. The quality of a generated object lives in the files on disk. How chattily the agent narrated its work is irrelevant.
- The rubrics had to stay external to the eval config. We keep rubrics as standalone markdown because they’re not only used by the eval. They’re also wired into the agent’s own feedback loop. The same rubric that grades a phase in CI is read by a reviewer subagent at runtime. Forking them into a YAML file owned by the eval tool would mean maintaining two copies of the truth.
- We wanted to use our own reviewer agents to produce scores. The reviewers already exist and already know how to fan out scorers and parse rubrics. A good eval tool should drive them and read their output, not force us to build a parallel scoring system.
- We needed fine-grained control over which phase we evaluate. A full pipeline run takes 10-15 minutes and costs around €10 in tokens. Running the full suite on every push isn’t practical.
What didn’t work
Tessl
Tessl’s scenario authoring is genuinely good. Defining a scenario as a task plus the criteria it’s judged against is the right primitive. But two things made it a non-starter.
The disqualifier: it doesn’t let the agent run inside a prepared folder that supplies the skill with the files it needs. For a phased build, that’s fatal. We can’t evaluate the “generate” skill in a vacuum; it needs the detailed plan from the previous phase sitting on disk. Tessl’s closest equivalent is bundling sample data and fixtures directly into task.md. Their own docs say: “if you need starting sample data or fixtures, those can be inlined into task.md.” Inlining is the wrong shape for us. A phase’s input is a directory tree of markdown, JSON, and code, not a blob you can paste into a task description. And once everything is inlined, you can’t tell what context a scenario depends on by looking at the folder structure.
The second problem: Tessl’s weighted_checklist grader evaluates the agent’s conversation transcript, not the files it wrote to disk. For skills whose entire job is to produce structured file artifacts, this is backwards. The score ends up depending on how verbosely the agent narrated its work. A structurally perfect output that the agent summarized loosely in chat scores lower than it should. The workaround of appending a step that prints full file contents into the conversation so the grader can see them is exactly the kind of thing that tells you the tool’s model and your problem’s model don’t line up.
Harbor
Harbor is built around Docker. Each evaluation is a task with an environment, defined by a Dockerfile and a task.toml that specifies CPU, memory, timeouts, and a verifier. The run loop: build the container, copy your files into /workspace/lab/, run the agent inside it, score.
For a lot of agent evaluation, that containerized model is a real strength: reproducible, isolated, safe. For us it was just heavy. We don’t need a sandboxed VM per scenario. We need to run a phase against a populated temp directory and read the files it writes. Docker added build times, image management, a –force-build dance whenever fixtures changed, and a layer of infrastructure between us and what we wanted to measure. Harbor solves a harder isolation problem than we have, and we’d pay for that overhead every single time.
Braintrust
Braintrust is a capable observability and evaluation platform, and on paper “LLM-as-judge over your outputs” sounds like what we wanted. In practice it was the wrong tool for an agent of this shape.
The biggest issue: its evaluation model is thin where we needed it to be thick. Our eval ended up being little more than a hand-rolled rubric prompt sent to the Anthropic SDK, with Braintrust wrapping the experiment tracking around it:
import Anthropic from "@anthropic-ai/sdk";
import { Eval } from "braintrust";


const RUBRIC = `You are a quality evaluator. Assess whether the lab
leverages its structure correctly. Score each criterion 1–4 ...`;


Eval("lab-quality", {
  data: () => [{ input: readFileSync(labDir + "/tasks.hcl", "utf8") }],
  task: async (input) => {
    const client = new Anthropic();
    const res = await client.messages.create({ /* RUBRIC + input */ });
    return res.content[0].text;
  },
  scores: [/* parse the 1–4 scores back out */],
});
At that point Braintrust isn’t evaluating our agent. It’s evaluating a prompt we wrote inside the harness. The platform’s center of gravity is observability and online experimentation. It’s not built for driving a multi-phase, file-producing agent and grading the artifacts.
There was also a sharper papercut: pulling Braintrust in as a dependency drags in a substantial amount of surface area unrelated to observability. The dependency tree picks up a full web framework (Express), a build tool with two dozen optional platform binaries (esbuild), a git client (simple-git), a Next.js environment loader, a Vercel serverless runtime, and a grab-bag of CLI display utilities. Something like 70+ transitive packages added to the tree. For a harness we wanted lean and auditable, that was hard to justify on its own, and it stacked on top of the conceptual mismatch.
Promptfoo: the one that nearly made it
Promptfoo was the best of the options we tested, and it’s worth being precise about why, because it got most of the way there.
The key differentiator: it could run the agent inside a populated, prepared folder. Promptfoo works with the Claude Agent SDK as a provider, with a configurable working directory and permission bypass:
providers:
  - id: anthropic:claude-agent-sdk
    config:
      working_dir: ../../../resources
      permission_mode: bypassPermissions
      allow_dangerously_skip_permissions: true
      append_allowed_tools: [WebFetch, WebSearch, Task]


prompts:
  - raw: |
      Read .claude/commands/<command>.md for your instructions.
      Proceed directly using {{input_var}}; do not ask for it.
That working_dir is the main enabler. A phase could execute against real upstream files. And the assertion model is flexible: we could mix a structural JavaScript assertion (does the file tree exist, do the JSON fields validate, does the count field match the array length) with an LLM rubric assertion, each with its own threshold. Promptfoo also supports an echo provider, which lets you skip the expensive agent run entirely and feed pre-generated output straight into the graders.
So why didn’t we keep it? Two reasons, both rooted in the requirements above.
The rubrics weren’t external in the way we needed. To use a markdown rubric with Promptfoo, we had to write custom JavaScript that read the rubric file, stuffed it into a meta-prompt, called the model, and parsed the JSON back out. This works, but notice what it is: a complete, parallel reimplementation of scoring, living inside the eval, duplicating logic our reviewer agents already perform at runtime. Promptfoo gave us no first-class way to say “drive my existing reviewer agent and read its scorecard.” The only path was custom JavaScript.
And that’s the second reason. There was no way, short of custom code, to use our review agents to produce the final scores. Promptfoo wants to own the grading step. We already had review agents with parallel scorer fan-out and rubric-aware logic, and we wanted the eval to use them, not replace them. Once you’re writing arbitrary JavaScript to bridge that gap, you’ve given up most of what the tool was supposed to provide.
Going custom
So we built our own. The whole suite is a small TypeScript harness that drives the Claude Agent SDK directly and maps one-to-one onto how the agent actually works.
The phased pipeline
The core abstraction is a Stage. Every build phase implements the same interface: it knows its number, the command it issues, how to build the prompt for a run, and which directory to run in.
export interface Stage {
  readonly number: StageNumber;          // 1..5
  readonly command: string;
  buildPrompt(config: RunConfig): string;
  cwd(workspaceDir: string, config: RunConfig): string;
}


export const STAGES: readonly Stage[] = [
  new ResearchCompanyStage(),   // 1
  new ResearchProductStage(),   // 2
  new PlanLabStage(),           // 3
  new PlanChapterStage(),       // 4
  new GenerateChapterStage(),   // 5
];
Running a stage is a query() against the SDK with the plugin loaded locally and permissions bypassed. We snapshot the workspace before and after so we know exactly which files the stage produced:
export async function runStage(stage, workspaceDir, config, env): Promise<string[]> {
  const before = snapshotFiles(workspaceDir);


  const q = query({
    prompt: stage.buildPrompt(config),
    options: {
      cwd: stage.cwd(workspaceDir, config),
      env: { ...process.env, ...env },
      plugins: [{ type: "local", path: PLUGIN_ROOT }],
      permissionMode: "bypassPermissions",
      allowDangerouslySkipPermissions: true,
    },
  });


  for await (const message of q) {
    if (message.type === "result" && message.is_error) {
      throw new Error(`Stage ${stage.number} failed`);
    }
  }


  const after = snapshotFiles(workspaceDir);
  return [...after].filter((f) => !before.has(f));
}
Fixtures and workspace isolation
The phased dependency problem (the one that eliminated Tessl) is solved with fixtures plus an isolated workspace. Each run creates a fresh temp directory, symlinks the plugin’s component folders into it so the SDK can resolve commands, agents, skills, templates, and references, and then copies in curated outputs for every phase before the one you’re starting from.
eval/fixtures/
├── 1-research-company-output/
├── 2-research-product-output/
├── 3-plan-lab-output/
└── 4-plan-chapter-output/
When you run –from-stage 4, the harness lays down fixtures 1 through 3 into the workspace, then runs phases 4 and 5 live. The later phase opens the workspace and finds exactly the upstream files it expects. There’s no inlining, no transcript inspection, no container. Just a temp directory that is in fact the real thing.
Reviewers grounded in rubrics
This is where the custom approach pays off most, and where every off-the-shelf tool made us duplicate scoring logic. The evaluation suite doesn’t grade anything itself. It runs our existing review agents and reads their structured output.
function reviewPrompt(stage, config, env): string {
  const labDir = env.LABSMITH_LAB_DIR ?? "";
  switch (stage) {
    case 3: return `Read ${PLUGIN_ROOT}/agents/review-lab-plan.md for your instructions.
                    Review ${labDir}/lab.md. Output format: json`;
    case 5: return `Read ${PLUGIN_ROOT}/agents/review-generated.md for your instructions.
                    Review the lab in the current directory. Output format: json`;
  }
}
One detail worth noting: we invoke the review agents directly rather than going through the interactive slash commands. When a command runs through the SDK, the scorecard can end up buried in a subagent’s output instead of the top-level result. Talking to the agent directly makes sure the final message published by the SDK is the scorecard.
The agent fans out its scorer subagents against the rubric files and returns a JSON array. The harness parses it with one explicit set of thresholds. These thresholds are the entire scoring policy, written once, in one place:
for (const e of entries) {
  (e.score === 0 || e.score === 1 ? checklist : analytic).push(toEntry(e));
}


const checklistPassed = checklist.every(c => c.score === 1);
const analyticMean = mean(analytic.map(c => c.score));


return { passed: checklistPassed && analyticMean >= 3.0 };
Checklist criteria must all pass. Analytic criteria are judged on a 1-5 scale and the phase passes when their mean clears 3.0. The rubrics stay as external markdown, owned by the agent and reused by the eval. No second copy of the truth. No parallel grading engine.
Triggering the right phase in CI
A full five-phase run costs roughly €10 in tokens. Running that on every push isn’t viable. A code change almost never affects all five phases. If you edit the detailed-planning agent, there’s no reason to re-run phase one’s research.
We encode the mapping from files to phases in a single YAML file:
entries:
  - { glob: "agents/company-researcher.md",               stage: 1 }
  - { glob: "skills/research-product/**",                  stage: 2 }
  - { glob: "agents/lab-planner.md",                       stage: 3 }
  - { glob: "references/evaluation/analytic/plan-lab/**",  stage: 3 }
  - { glob: "agents/chapter-planner.md",                   stage: 4 }
  - { glob: "agents/chapter-implementer.md",               stage: 5 }
  - { glob: "references/evaluation/checklist/generate/**", stage: 5 }
A pre-commit hook enforces that every file under the plugin is covered by at least one entry. A small script diffs the changed files against this map and emits the lowest affected phase. The fallback is deliberately conservative: an unmatched file, a missing base ref, a shallow clone, or a brand-new branch all default to a full run from phase one.
The GitHub Actions workflow wires it together. It triggers only on changes under the plugin path, computes the start phase from the diff, and runs the eval forward from there:
on:
  pull_request:
    paths: ['plugin/**']


- name: Compute from-stage
  id: stage
  run: node eval/scripts/compute-stage.mjs "$BASE"


- name: Run eval
  run: node dist/src/cli.js --from-stage ${{ steps.stage.outputs.from_stage }}
  env:
    ANTHROPIC_API_KEY: ${{ secrets.ANTHROPIC_API_KEY }}
In practice this turns a €10 worst case into a few euros for the common case, since most iteration happens on the generation and review logic.
Why agent eval tooling is still immature
Every real agent has an architecture that lives past the list of its skills, subagents, and context files. Those are the visible elements. What’s harder to see is the coupling between them: the web of dependencies that determines how the agent actually behaves.
The sharpest example for us is the coupling between phases, and it’s entirely informal. Each phase reads the files the previous phases produced and produces files the next phases will read. But nothing declares which files those are, what shape they take, or which fields downstream actually depends on. Phase four parses the plan phase three produced to find a slug. If phase three changes the heading that slug lives under, phase four silently reads nothing. Phase five expects a particular structure in phase four’s detailed plan. Widen or rename a section and generation degrades without an error. None of this contract is written down anywhere a tool or a new teammate can see.
That’s why the modern eval tools stop where they do. They’re excellent at what generalizes: scenario authoring, transcript capture, trajectory evaluation, LLM-as-judge over a string, experiment tracking. But they all assume the thing under test is roughly a function from input to output. The moment your agent does complex, phased, workflow-style work, you’ve left the problem space those tools were built for.
The abstraction they’d need from us doesn’t exist yet. We can’t fully describe the coupling, so we can hardly expect a tool to acknowledge and build on it. Until there’s a shared language for an agent’s internal architecture, something richer than frontmatter, that captures the dependencies between phases, artifacts, rubrics, and reviewers, general tools will keep topping out at trajectory evaluation.
When to go custom
For a great many real agents a small custom harness that speaks your agent’s actual structure, drives it through the same SDK it runs on, reuses the graders it already has, and runs only the part of itself that your change – is the way to go.
If your agent is really a single prompt with a judge, use the great tools that exist. If it’s a coupled, phased system, don’t fight a tool into a shape it was never meant to hold. Write the hundred lines that match your architecture. For now, that’s still the way.